Qwen
Qwen3.8-27B Achieves 144 Tokens Per Second on Max M5 Processor
Qwen3.8-27B achieved an inference speed of 144 tokens per second on the Max M5 processor, marking a significant step for local AI execution on mobile hardware.
SSICT News ·
Latest News

Daily AI Roundup Covers Qwen3.8 Architecture and Agent Integrations
The latest updates cover Qwen3.8-Flash-Next architecture, ClaudeDevs Admin API tools, and new Grok voice agent integrations in LiveKit.
Apple Partners with Alibaba to Train AI Model for Chinese Market
Apple has partnered with Alibaba to develop a localized AI model for the Chinese market, marking a shift in its regional software strategy.
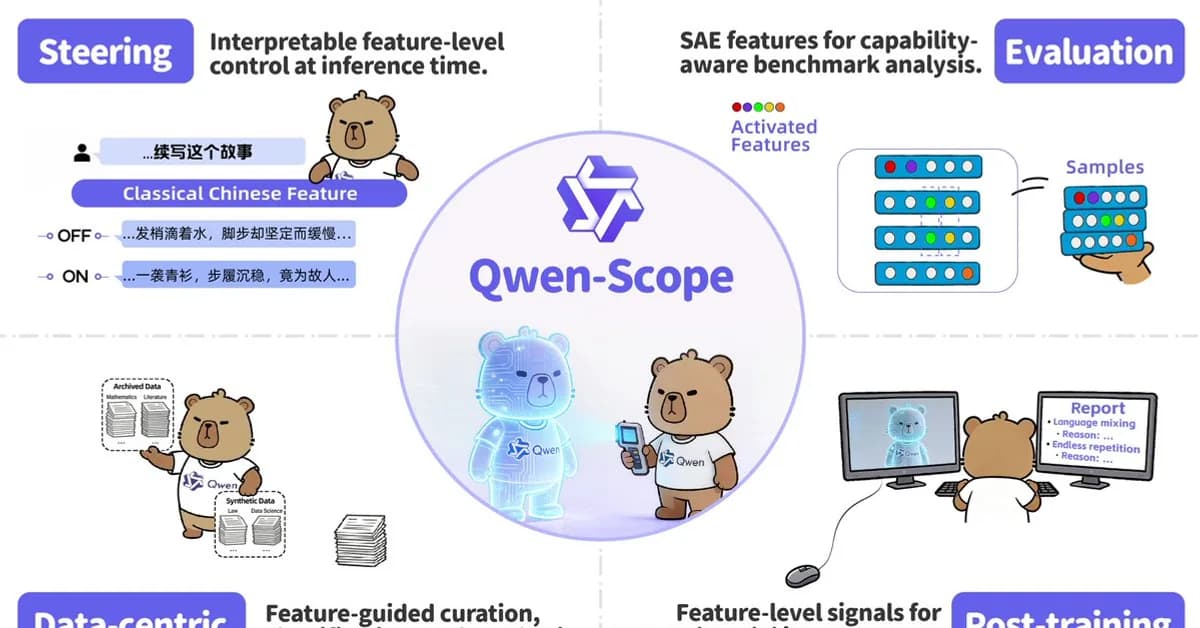
Alibaba Qwen Releases Qwen-Scope, Open Suite of Sparse Autoencoders
Alibaba releases Qwen-Scope, an open suite of sparse autoencoders enabling direct manipulation of model features, data classification, and model behavior analysis without prompt engineering.

HONOR and Alibaba Announce Strategic AI Collaboration
Pioneering a new era of AI-driven mobile experiences through comprehensive cloud-device integration. [Riyadh, KSA] HONOR and Alibaba officially cemented a landmark strategic cooperation agreement in Hangzhou, China. James Li, CEO of HONOR Device Co., Ltd. and Eddie Wu, CEO of Alibaba Group, jointly witnessed the signing. This pivotal strategic cooperation agreement is built upon a […]